Every leading AI model, in one creative cloud
Images, video and sound from the models creators actually use. See them side by side on the same prompt, then make your own.
Compare
Same prompt, five models
Every model has its own eye. One prompt, one try each, same aspect ratio.
Cinematic editorial photograph of a small lighthouse keeper’s cottage on a stormy rocky coast at golden hour, a woman in a yellow raincoat standing on the porch, dramatic clouds breaking with warm light, wet stones, shallow depth of field
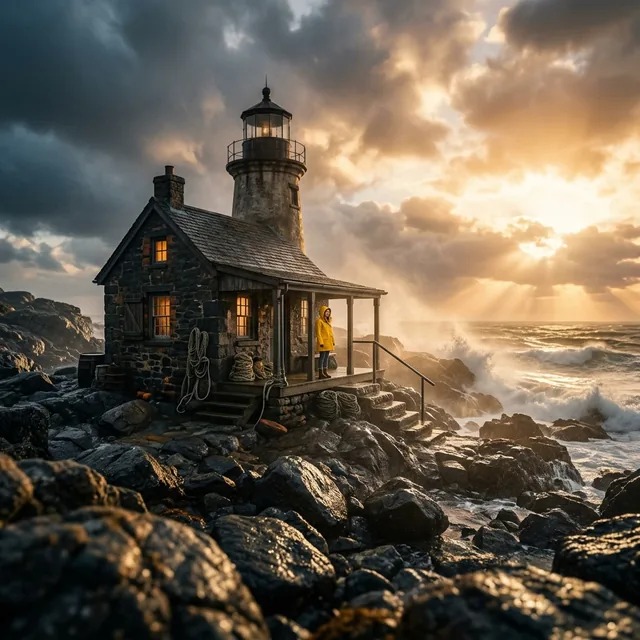
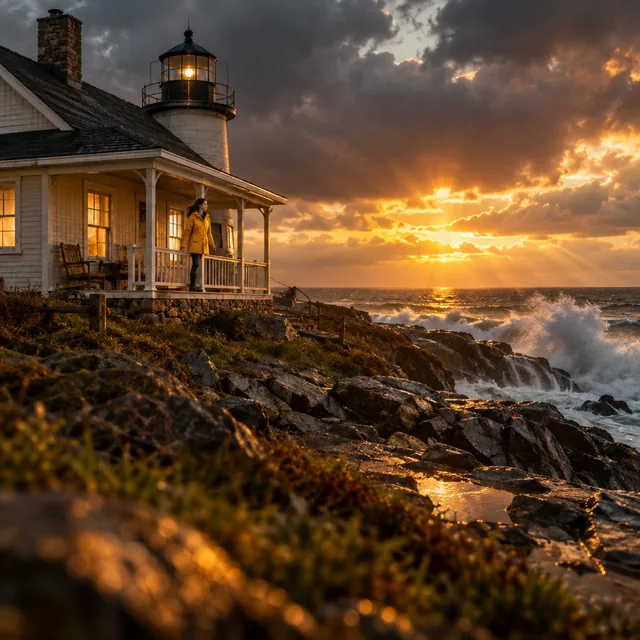
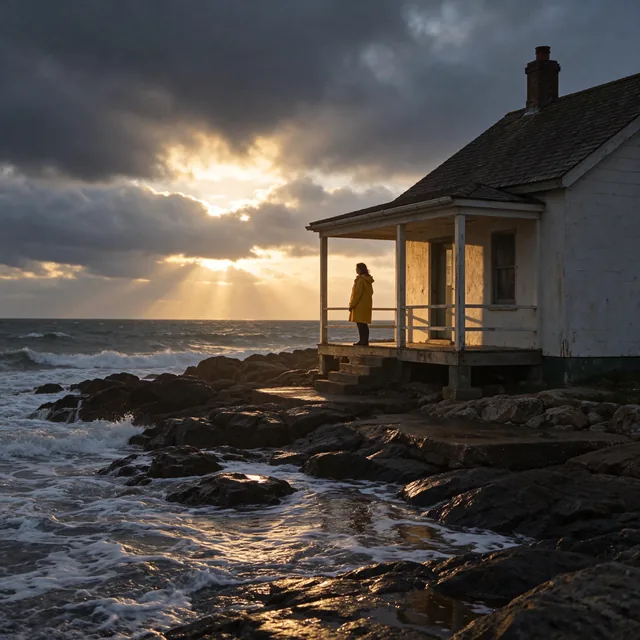
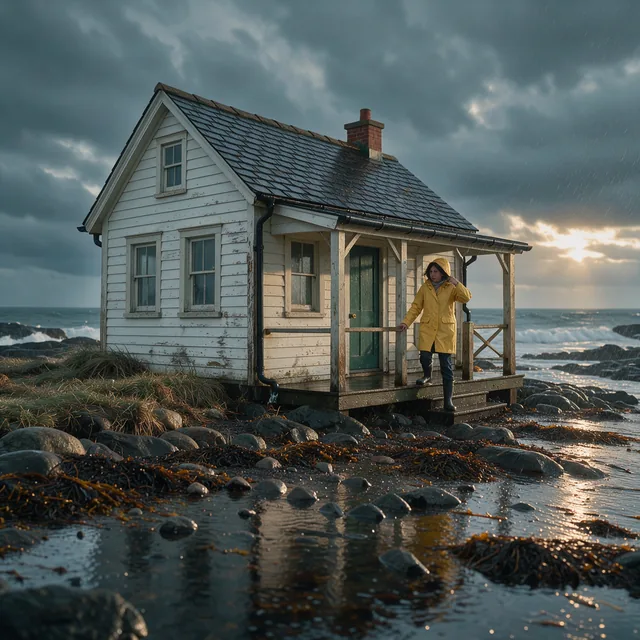
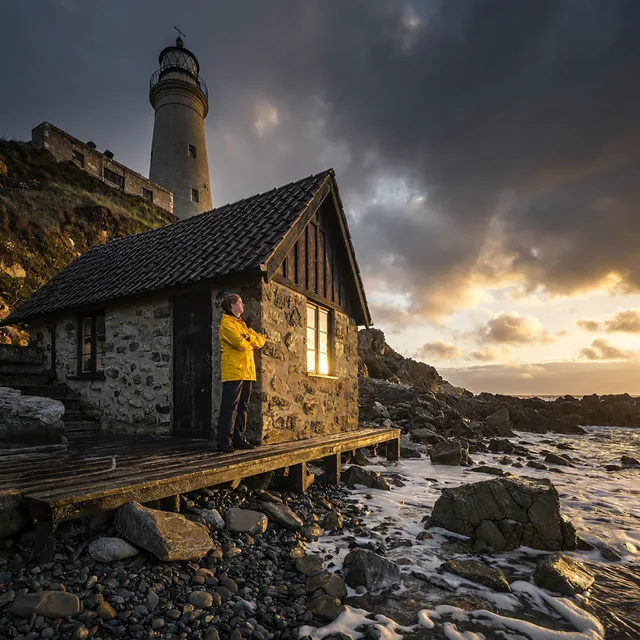
First result from each model. No re-rolls, no editing.
Create
From a still to a scene
Photographs, illustrations, architecture and motion, all from a sentence.
Bring a still to life
The clip above was animated from the still image on the right.
 Image
Food and product
Seedream
 Illustration
Any art style
GPT Image
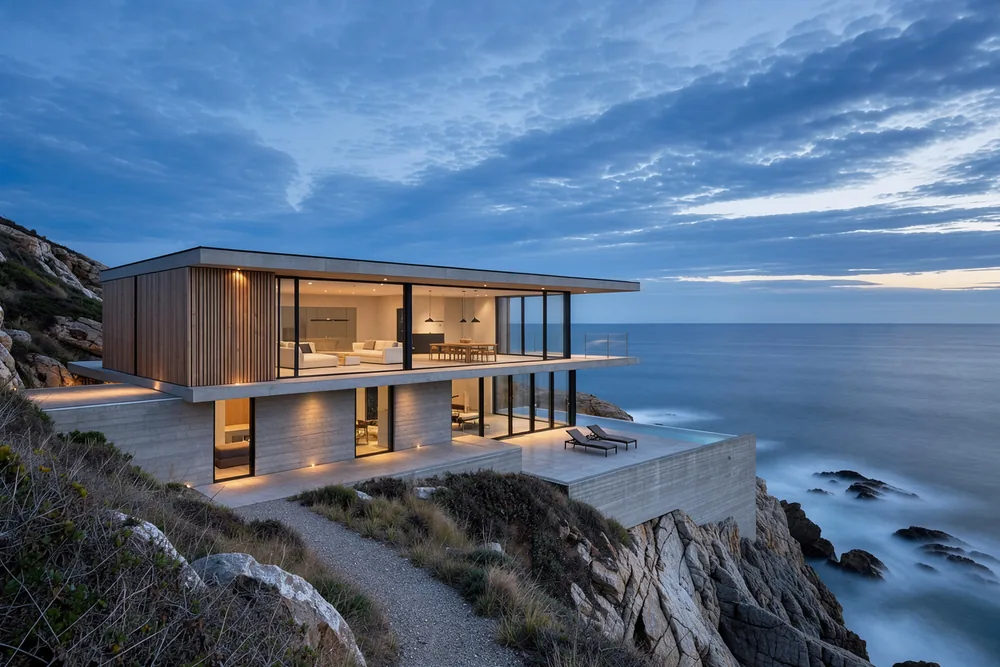 Image
Architecture
FLUX
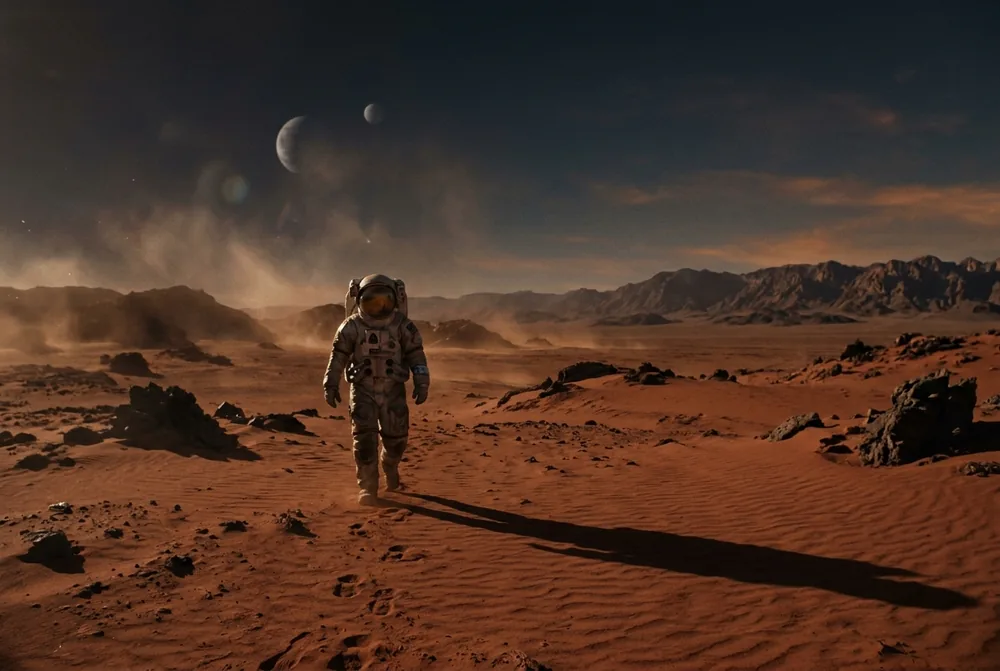 Still · source
Concept art
Nano Banana
How it works
Three steps, no manual
Say what you see
Describe the subject, the mood and the place in plain words. Many models expand a short prompt for you.
Pick the model
Photoreal, illustrated, typographic or animated: choose the model that fits, or try several on the same prompt.
Refine and extend
Edit the image, animate it into video, add a voice or a soundtrack, then take the files into your project.
Use it for
Made for people who make things
Marketing visuals
Campaign images and product shots in many looks, quickly.
Social video
Short clips from a still image or a single line of text.
Concept art
Explore worlds, characters and moods before committing.
Storyboards
Turn a script into frames, then into moving shots.
Voice-over and music
Narration in many languages and original music from a prompt.
Editing and variations
Change a background, an outfit or a color and keep the rest.
Models
What each one is good at
Model names and trademarks belong to their owners.
Image
- Nano BananaGeneration and editing up to 4K, strong prompt adherence.
- GPT ImageHigh-quality generation and editing from natural language.
- SeedreamPhotographic realism and multi-reference editing.
- FLUXDetailed composition and crisp typography.
- MiniMaxPhotorealistic images with built-in prompt enhancement.
Video
- KlingText, image and reference to video, plus editing and extension.
- Veo1080p clips with synchronized audio.
- SeedanceCinematic clips with native audio.
- WanText and image to video with audio, flexible duration.
Audio
- ElevenLabs speechExpressive multilingual text to speech.
- ElevenLabs musicSongs and instrumentals from a text prompt.
- Sound effectsEffects and looping ambience from a description.
- DubbingTranslate video and audio while keeping the speaker’s voice.
FAQ
Good to know
AtlasCloud AI is an independent showcase of the AI creative suite. It compares the leading image, video and audio models with real outputs, and links to third-party platforms where you can run them.
One prompt was sent once to each model, with the same aspect ratio and default settings. The first result from each model is shown, with no re-rolls and no editing.
Image: Nano Banana, GPT Image, Seedream, FLUX and MiniMax. Video: Kling, Veo, Seedance and Wan. Audio: ElevenLabs for speech, music and sound effects.
Yes. Image-to-video models animate a still from a text description of the motion. The video on this page was made that way from the astronaut image next to it.
That depends on the model and on the platform you use. Check the licence and terms on the platform before you publish or sell anything.
They open one of several third-party AI platforms that host these models. Pricing, accounts and licence terms are set by the platform you land on.
Make something new
- Image, video and sound
- Compare leading models
- Start from one sentence